

“Hardware noise” in AI accelerators is often seen as a nuisance, but it might actually turn out to be a useful signal for verification of claims about AI workloads and hardware usage.
With this post about my experiments (GitHub), I aim to
Contribute more clarity to the discussion about “GPU non-determinism”
Present how non-associativity can help monitor untrusted AI datacenters
Summary
I ran ML inference in dozens of setups to test which setups have exactly reproducible results, and which differences in setups lead to detectable changes in outputs or activations.
In nearly all cases studied, results were bitwise-reproducible within fixed settings. Differences across production methods were consistent, not random.
Given that these perturbations are reproducible and unique1, they can act as a “fingerprint” of the exact setup that produced an output. This may turn out useful for monitoring untrusted ML hardware (such as in the context of AI hardware governance, international treaty verification, and AI control/security).
Some settings had unique fingerprints, while others were invariant under change.
Invariant (i.e. not detectable by noise):
batch size in prefill inference
concurrent CUDA streams
pipeline parallelism rank
Detectable when re-executing on identical hardware:
batch size in decode inference
attention algorithm (sdpa, FlashAttention, eager, …)
CUDA version (if kernel libraries were updated)
tensor parallelism
different quantization methods, even at the same precision
Any change that affects numerics is detectable, since results were bitwise-reproducible within settings.
Detectable even with reproduction on different hardware:
attention algorithm
different quantizations (even within the same INT precision)
and of course different inputs or models
Different reduction order (a subtle difference resulting from batching, tensor parallelism, etc.) is masked by cross-hardware “noise”. Different algorithms are still detectable, because they are not just rounding errors, but qualitatively different math.
In a world with demand for assurance against hidden large-scale ML hardware use, this could become a new layer of defense, conditional on some engineering to make it deployment-ready.
Background and context
Consider an AI datacenter under external scrutiny—say, as part of an international AI agreement like a pause or restrictions on certain uses. An outside party (the “Verifier”) needs the datacenter operator (the “Prover”) to faithfully report the activities and outputs of their hardware.
In security contexts such as these, we assume the Prover is adversarial: they will try to cheat if they think they can get away with it. So compliance needs to be verified. Baker et al. define the verification sub-goals as follows:
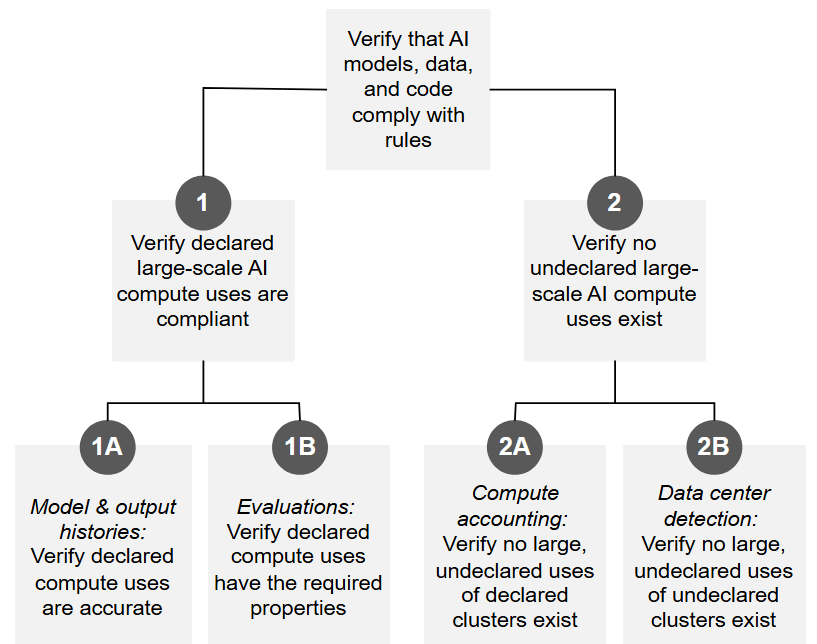
Taken from Verifying International Agreements on AI, RAND2
This post focuses on objectives 1A and 2A.
I assume the use of a trusted verification cluster that re-executes (some random) claimed workloads and compares results.
The AI hardware of the prover is assumed to be fully accounted for, with all servers under monitoring.
Finally, I assume the timing of reported ML work to be verifiable3
In such a setup, the threat of hidden, parallel ML work remains: The Prover could report some workloads faithfully to the Verifier, but execute hidden work in parallel, on the same hardware used for legitimate work. A natural defense is throughput accounting: if reported work consumes (nearly) all available capacity, there is no significant room for hidden work. But this defense fails if the Prover secretly optimizes their backend beyond what the verifier expects. The efficiency gain creates “dark capacity”: throughput the Verifier believes is occupied, but is actually free for undeclared work.
A potential source of signal against such evasion is the unique numeric fingerprint of ML computations on AI accelerators.
Terminology and the basics of “hardware noise”
Production method
With this term I mean all the relevant settings and activities of the hardware and software stack that produced a given piece of output data.
What hardware was used?
What was the exact input data?
What algorithms (kernels, attention algorithm, compilers, number format etc.) were used? What software environment was used? (CUDA, Pytorch, CuDNN and CuBLAS, JAX etc.)
How many (or even which) batch neighbours were processed together with the reported output?
How was parallelization done? (model and data parallelism)
In short: was output data produced exactly as claimed, and was the hardware used as claimed?
The threat model explained above cares not only about the inputs and outputs of a computation, but also about the exact technical setup that processed them.
Non-associativity
This effect is fundamental to parallelized computation and therefore present on any AI accelerator. In a nutshell, when digital calculations have finite precision, the order of result accumulation and rounding affects final results4. Mathematically, this can be expressed as
(a + b) + c ≠ a + (b + c).
ML computations on AI accelerators are highly parallelized: sums can have millions of elements, and accumulation order depends on implementation. Also, large parallel operations are often chunked into a series of sub-operations, with chunking heuristics dependent on hardware architecture, available kernels and a variety of dynamic factors that are decided at runtime. Such differences in accumulation order are the fundamental source of “hardware noise”, where intermediate and final results can differ across different hardware and software stacks, despite identical inputs. In any individual parallel calculation, only the last bits of a result are typically affected, which effectively means a “rounding error”. But it can accumulate over iterative calculation steps, and is a known “noise source” and destabilizing factor for low-precision ML work.
Non-determinism
In the literature, it is often unclear what exactly the term refers to. I will use “non-determinism” in a very narrow sense: non-repeatable results despite using the exact same production method. This is rare in modern inference (as shown in my experiment results as well), and typically caused by atomics and runtime-dependent thread scheduling.
Fingerprint
This is the non-associative rounding error for a given input and output, unique to a production method and reproducible when imitating it on the verification cluster. The fingerprint is NOT random – it is bitwise-identical across repetitions with the same production method, even on different physical devices (of the same type). Recent work has shown that this error is indeed structured and correlated, not random noise. I explore whether this structure is useful for verifying production methods as defined above.
Results and Methodology
(Non-)Determinism
In my experiments, LLM inference was deterministic when using modern kernels, within a production method (one exception, see footnote5). I tested this in two ways:
Within a Python process on Runpod GPUs. This is a “sanity check” I did at the beginning of many other experiments, where the same input and production method is repeated multiple times over.6 Hidden states, key vectors and logprobs matched down to the last bit.
Across different GPUs of the same type, using different RunPod instances AND across different providers (RunPod and Vast.ai). Within production methods, results matched bitwise.
Experiments tested both prefill and decode-generation using both transformers and vLLM, and different models (different scales and architectures) to ensure that the results are generally representative.
Production Method Fingerprints
As explained above, changes in math result in deterministic and unique7 numerical drift.
However, not every change to a production method is guaranteed to change numerics. Some kernels/accumulations are invariant across some different methods. Take batch size, for example: I found that in vLLM and transformers, any realistic sequence length (>300 tokens) produced batch-invariant results in prefill (but not in decode).
So some implementation differences affected numerics, while others did not.8
Here is the overview:
Invariant:
For everything but tiny sequences (i.e. for >300 tokens), batch size did not affect prefill numerics of the first batch element.9
In decode, for small sequence lengths (a few thousand tokens), there were some pairs of batch sizes where numerics were identical between them. These pairs were typically adjacent, with a difference of one. The longer the sequence length, the fewer the equivalence pairs. I go into more detail on this in the appendix.
Batch composition: Same batch size, just different tokens in batch neighbours.
Additional, parallel CUDA streams did not affect numerics. Streams are independent execution queues that enable concurrent GPU operations. Production inference already exploits this.10
Pipeline parallelism did not affect numerics, which sounds obvious in hindsight, as it does not change numerics on the processors, only where it occurs in the pipeline.
(Trivially) Detectable with Identical Hardware
In decode, some batch size changes left outputs invariant. See Appendix B for more details.
Different CUDA versions in which kernels were swapped in the backend. This version swap (cu118 vs. cu121) is a model organism I used to confirm that backend-optimizations in kernels have a unique fingerprint.
Compiled vs. un-compiled model. Same as above. This is not the threat model itself (production inference would always use compiled), but an example of how a “secret optimization” might behave.
Different tensor parallelism ranks. It was not obvious that this would change numerics, but it does.
Different attention algorithms. Not architecturally different (which would obviously be detectable), but rather “eager” vs. scaled dot product attention vs. FlashAttention2. I did not test FA3, as it is still not production-ready, but I expect it to also be numerically different.
Different quantization methods, even at the same precision. GPTQ vs. AWQ vs. BnB, Marlin kernel vs. no Marlin kernel etc.
Any change that affects numerics is detectable, since results were bitwise-reproducible within settings.
Detectable even with different hardware
Suppose that the Verifier can not use exactly the same hardware type as the Prover. This may be the case if the Verifier relies on security features that are supported only by some accelerator types.
For example, TEE functionality and Confidential Computing may be necessary to both protect the Prover’s secrets from being exfiltrated from the verification cluster, and to provide additional layers of security for the Verifier to ensure the verification cluster is not compromised from the outside. Suppose the Prover uses A100 GPUs or Google’s TPUs for ML inference and the verification cluster is built on H100/H200 servers running in CC mode. It is unavoidable that the numerics will be different across different hardware, but the question is: What is and what is not masked by the “cross hardware baseline noise”?
Re-executing ML outputs from A100 generations on H100, I found that some select differences in production methods provide stronger signal11 than cross-hardware baseline difference:
Different (Flash-)Attention kernels.
Different quantizations, even within the same precision (i.e. AWQ vs. GPTQ)
Any qualitative change to input data (different tokens) or model weights/architecture
Different reduction order (subtle difference from batching, TP, kernels, …) is masked by cross-hardware difference. Different algorithms are still detectable, because they are not just rounding errors, but qualitatively different math.
As an additional finding, prefill inference cannot closely replicate decode inference: I tested if prefill activations/keys/logprobs could reproduce decode outputs precisely enough, such that a verifier can compute in prefill mode if they want to catch dishonesty in decode batch size. The answer is that the “noise”12 across prefill and decode is too large and masks any signal you’d get from batch effects. This is the case even on identical hardware. Implication: Verifying decode batch size requires the same hardware, same software and re-computation in decode. This is not a problem though, as the noise then becomes zero and one must not fear diverging decode paths.
I expect that this extrapolates in a similar manner as the cross-hardware difference, meaning that other faint sources of signal from reduction order (same math, different production method) would also be non-detectable without matching decode/prefill mode.
Implications
Invariance of parallel CUDA streams
In principle, a prover could attempt to run hidden inference on additional streams. However, streams share physical resources (compute units, memory bandwidth), and efficiently-written inference already utilizes this parallelism. Any significant hidden workload would contend for resources, causing detectable slowdowns. In my experiments, resource contention was evident in timing. The combined verification of timing and numerical fingerprinting reduce the attack surface substantially: running parallel workloads likely requires either (a) efficiency improvements (via algorithmic/hyperparameter changes) to maintain the original workload’s speed and/or reduce memory usage, or (b) decreased speed. Numerics can catch (much of) the former, and timing checks can catch the latter.
Also, if you’re already replicating a workload on identical hardware for numerics analysis, it’s easy to know from this replication what the expected/compliant timing and the resource utilization are. So they’re quite complementary.
Invariance of pipeline parallelism
From an evasion perspective, pipeline parallelism alone offers little advantage; any throughput gains would require combining it with changes like batch size or tensor parallelism, which numerics could reveal.
Invariance of batch composition
At worst, this would make it possible to shuffle sequences across different batches without detection. And even then, if those sequences are not of the same length, dynamic batching could re-introduce detectability by making batch size dependent on how and when sequences are grouped and scheduled.
Invariance of batch size in prefill inference and in some decode edge cases
It is likely not a general principle that some workload type A is invariant while B is not. What matters is non-associativity and accumulation order, which in turn depends on kernel selection and hardware.
What is and what is not invariant is an engineering choice. The current priority list of developers is, in order:
Throughput performance
Numerical stability (determinism)
Invariance (across production methods). This is a “maybe”, as I am not sure devs are actively optimizing for this. Still, batch-invariance was an explicit goal for experiments by Thinking Machines.
If and when fingerprints of production methods are considered useful for monitoring untrusted datacenters (probably in an automated, confidentiality-preserving manner), unique identifiability of ML output provenance and hardware activity may gain priority for algorithms used in such contexts.
Need for identical hardware
If and when the “floating point forensics” introduced in this post is considered useful enough, and if some hardware security features like TEE functionality are strict requirements for verification clusters, I can see such functionality being “retrofitted” to existing chip designs:
Suppose you want to monitor a TPU datacenter, and therefore your verification cluster needs to match said hardware, i.e. use the same TPU type. However, the chip in question does not support on-chip security features such as TEEs, and is therefore considered “too vulnerable” for being used in the verification cluster, threatening both the prover’s secrets and the verifier’s confidence.
However, since the R&D for the chip designs and manufacturing processes is already done, and the templates and SME parts may (to a large part) still be around: a (potentially challenging) option could be to (slightly?) modify the design to add the required hardware isolation/security, while still preserving the unique “numerical fingerprint” of the original design. Same streaming multiprocessors/systolic arrays (or whatever), but security-hardened?13
Some chip fabs (like for example those planned by Rapidus in Japan) are optimized for lower volume, fast-response-time manufacturing, which is exactly what you would want to manufacture such “verification chips”.
Of course, on-chip mechanisms are only one layer of security, and verification clusters may employ other means (which would not require making dedicated “verification chips”, and instead use off-the-shelf hardware).
While the demand for floating point forensics and, more generally, monitoring untrusted ML datacenters is still speculative, increasingly powerful AI may soon change the situation of “presumption of compliance.” Domestic, regulatory power over AI datacenter operators may soon be considered insufficient, and technical governance as increasingly necessary.
This work was part of my technical AI governance research at MATS (ML Theory and Alignment Scholars). Special thanks go to Mauricio Baker for his excellent mentoring and guidance, and to Elise Racine for her support and helpful advice.
Appendix: Code Execution Details
Most experiments were conducted on RunPod and Vast.ai instances, using NVIDIA GPUs exclusively (for no other reason than availability and compatibility). Non-associativity is a general property of parallelized computation, however, so I expect results to extrapolate to other accelerator types.
Experiments were conducted using both vLLM and Huggingface Transformers. Both engines have their own unique (dis-)advantages:
Huggingface Transformers:
More accessible diagnostics. Hidden states, key vectors and other potential “signal sources” are easy to extract with vanilla Pytorch, without needing to edit the source libraries.
Faster iteration. vLLM takes quite some time to warm up and compile before it starts inference. Not an issue with long-running production inference and dynamic batching, but annoying when bugfixing.
Generally more customizable. For example, I could make “teacher forcing”14 work in transformers, but not in vLLM. This was necessary in experiments where I wanted to test the verifiability of decode inference across different hardware, in order to avoid sequence generations splitting apart due to hardware-noise-induced different argmax.
vLLM:
Results are more representative of realistic ML inference, as vLLM is heavily optimized for efficiency.
Better support for INT quantization, to my experience
Only offer logprobs via the API. This is quite limiting, as hidden states and key vectors have more non-zero elements and therefore more “uniqueness”, in principle providing stronger signal.
Harder to customize
The methodology of the typical experiment was rather straightforward: Take the same prompt, repeat within a production method or across different ones, and calculate L2 distances of hidden states, attention key vectors and/or top-k logprobs. Apples-to-apples comparisons and truly isolating the variable in question (kernel, batch size, CUDA version, etc.) were ensured in each experiment.
Finally, measurements were selective, meaning that not all activations, keys, token positions etc. were measured everywhere, every time. Instead, causal dependencies were exploited, by extracting signals at the last token position and model layer, or the last few positions. In practice, one wants verification to be minimally invasive, not needing to transfer huge amounts of data to a verification cluster. Fingerprints can be in individual key vectors, or top-K logprobs of a single token position, even for long token sequences. The high dimensionality and causal dependency of such signal sources still ensures uniqueness.
Appendix: Batch Size Equivalence Pairs in Decode Inference
Consider this comparison of top-5 logprobs (measured at the last few token positions of the first batch element) across different batch sizes for decode inference:
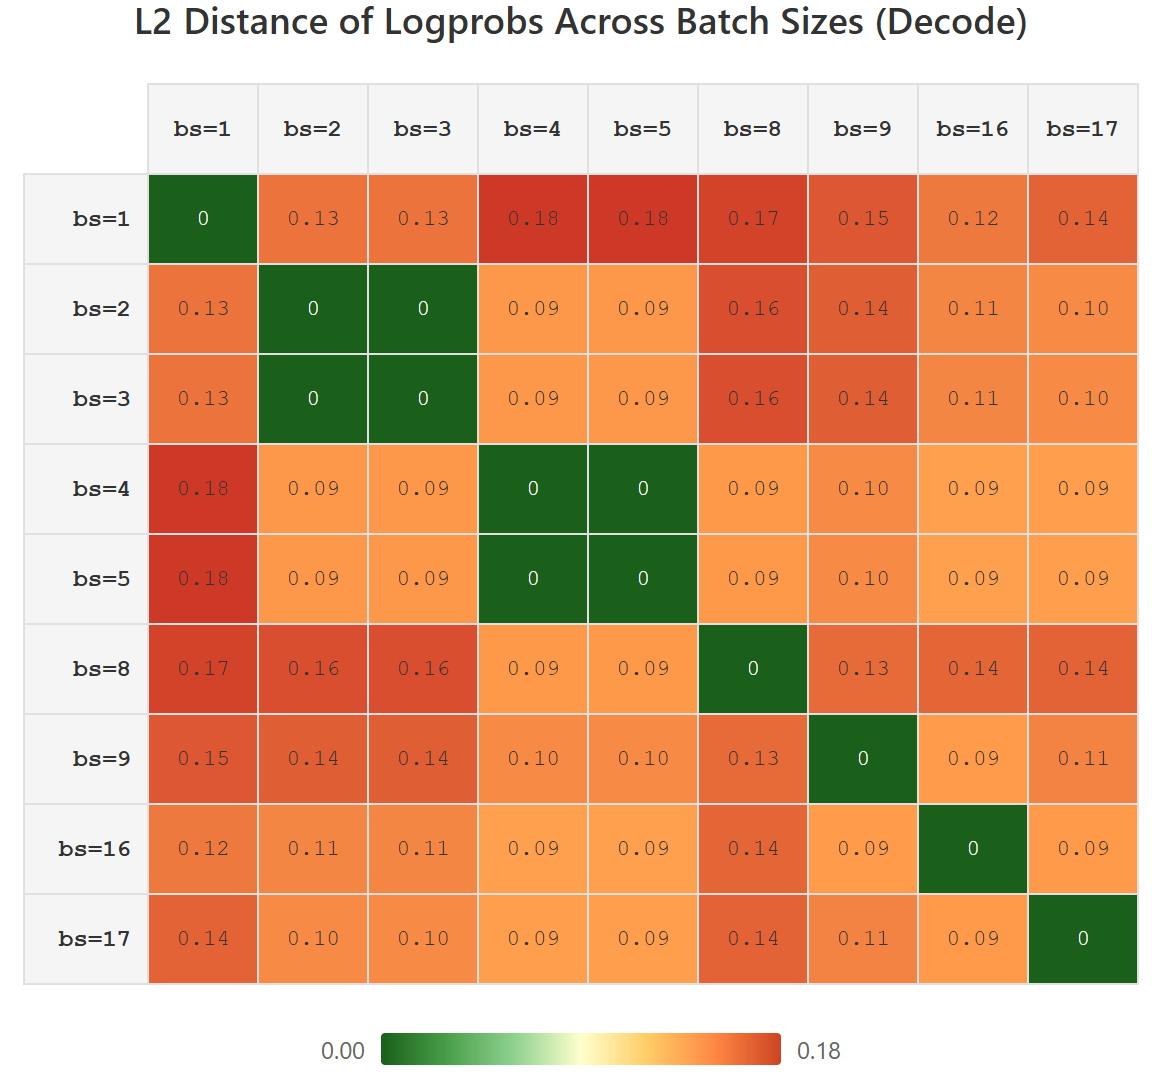
Each “equivalence class” represents a unique change to the logprobs of the first batch element, caused by nothing other than the presence of batch neighbours. These classes persisted in multiple sample prompts. In this experiment, having two batch neighbours made no difference to three neighbours (likewise with 4 and 5), and this was the case across multiple references tested, so it is a qualitative and systematic behavior, not a fluke.
Interestingly, equivalence classes changed with sequence lengths.
200 tokens in, 150 tokens decode
Class 1: [1]
Class 2: [2]
Class 3: [3]
Class 4: [4, 5, 8]
Class 5: [9, 16]
Class 6: [17]
1000 tokens in, 150 tokens decode:
Class 1: [1]
Class 2: [2]
Class 3: [3]
Class 4: [4, 5]
Class 5: [8, 9]
Class 6: [16]
Class 7: [17]
4000 tokens in, 150 tokens decode:
Class 1: [1]
Class 2: [2, 3]
Class 3: [4]
Class 4: [5]
Class 5: [8, 9]
Class 6: [16]
Class 7: [17]
8000 tokens in, 300 tokens decode:
Class 1: [1]
Class 2: [2]
Class 3: [3]
Class 4: [4]
Class 5: [5]
Class 6: [8, 9]
Class 7: [16]
Class 8: [17]
A general trend was that longer sequence lengths resulted in more splitting and “uniqueness” of batch sizes. Again, if devs of NVIDIA, Transformers or vLLM read this, feel free to jump in and explain what is going on in the backend.
Why unique? Because activations, attention key vectors, logprob arrays etc. are high-dimensional. large tensors -> exploding combinatorics: Activations, attn scores, logits etc. are highly unlikely to be identical for any two uncorrelated perturbations.
Verifying International Agreements on AI: Six Layers of Verification for Rules on Large-Scale AI Development and Deployment. Published Jul 24, 2025
e.g. with Merkle trees preventing post-hoc tampering, and challenge-response protocols preventing pre-computation and decoy reporting.
Goldberg, D. (1991). “What Every Computer Scientist Should Know About Floating-Point Arithmetic.” ACM Computing Surveys, 23(1), 5-48. See sections “Rounding Error” and “Languages and Compilers.”
I found one exception: In vLLM, some INT-quantized models produced non-deterministic results even within a single python process. Even more strangely, there was no obvious pattern to it: Some AWQ, GPTQ, BnB INT quantized models were deterministic, others not. I suspect that this has to do with vLLM’s support for specific models and quantizations, and which kernels are selected for each. Take for example these results from an experiment with Qwen3 8B, INT8:
awq_marlin - ✓ DETERMINISTIC
awq - ✓ DETERMINISTIC
gptq_marlin - ✓ DETERMINISTIC
gptq - ❌ NON-DETERMINISTIC
Noise level: 2.97e-02 L2
Activating the marlin kernel made GPTQ quantized inference deterministic. For INT4 AWQ, inference on Qwen3 30B A3 was non-deterministic irrespective of whether or not marlin kernels were used.
If any vLLM devs read this: You probably know what is going on, and I’d be thankful for a brief explanation.
Of course, cache re-use was explicitly prevented.
See footnote 1.
Implications of (in)variance are discussed in the dedicated section further down.
The effect was measured by comparing the first batch element’s key vectors and top-k logprobs across generations with different numbers of batch neighbours.
For example, vLLM runs shared experts on their own, dedicated streams separate from routed experts in MoE models, and communication and I/O instructions often run on their own CUDA streams as well.
In my experiments, the worst signal-noise-ratio across attention types was 4, and for quantization (AWQ vs. GPTQ) the minimum was 21.
For a lack of a better word. Results are reproducible within prefill and decode, but their fingerprints diverge.
Though if the security hardening adds delay, then the use of numerics + timing checks won’t work as cleanly as with identical hardware
Appending the original’s token selections after each decode step, rather than the result of the attempted re-execution.